Table of Contents
Millions of people use Microsoft Outlook, Teams, and other Microsoft 365 applications every day without thinking much about the technology running behind them.
You open Outlook, check your emails, join a Teams meeting, and continue working. Everything usually happens within seconds.
But on 12 November 2026, that routine was interrupted.
A major disruption to Microsoft’s cloud infrastructure left users around the world struggling to access Outlook mailboxes and several connected Microsoft 365 services. By Friday, 13 November, the company was still working to restore affected systems.
What makes this incident particularly interesting is how the problems developed. According to Microsoft’s technical updates, servers became unavailable, traffic shifted to other systems, and some recovery attempts initially failed to keep services running.
So, what actually went wrong inside Microsoft’s infrastructure? And why did a problem affecting Outlook also interfere with Teams, Copilot, and other applications?
Let’s look at what Microsoft has confirmed so far.
How Did the Microsoft 365 Outage Begin?
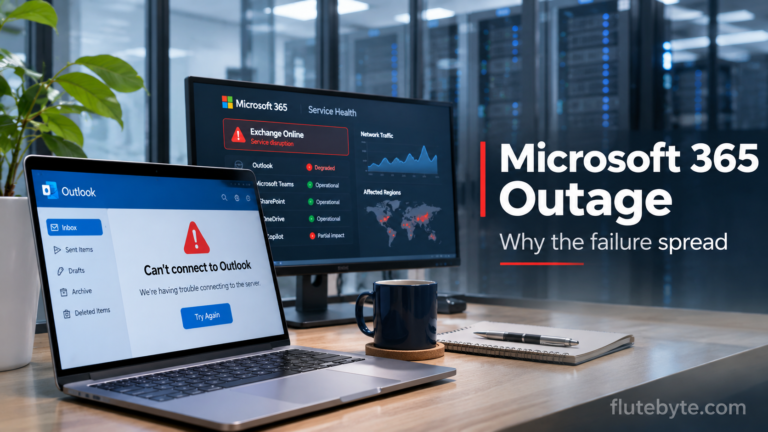
According to Microsoft’s service health records, the Exchange Online incident began at approximately 4:17 PM UTC on 12 November 2026, or 9:47 PM in India.
Users began experiencing problems accessing their email accounts through Outlook on the web, desktop applications, and mobile devices.
Exchange Online is Microsoft’s cloud-hosted email platform. It handles business email, calendars, mailbox access, and several related services used throughout Microsoft 365.
As connectivity problems spread, Microsoft identified unusually high loads across parts of its infrastructure.
Initially, engineers investigated whether an unexpected increase in service traffic was responsible.
However, Microsoft’s investigation soon revealed something more complicated.
A significant number of servers had become unexpectedly unavailable. As a result, the remaining servers were forced to handle additional requests.
This reduced the amount of infrastructure available to serve users and created further connectivity problems.
By the time Microsoft began restoring individual servers, the disruption had already affected services across multiple regions.
What Actually Caused Microsoft’s Servers to Stop Responding?
One of the most important findings from Microsoft’s investigation involved its automated server health checks.
Large cloud platforms constantly monitor their infrastructure to determine whether servers are operating correctly.
These checks help the system identify servers that are healthy enough to receive user requests.
During the outage, Microsoft found that some servers were failing these health checks and becoming unavailable.
Engineers also discovered that a process responsible for establishing secure connections was becoming overwhelmed.
When this happened, affected servers could stop processing requests.
There was another problem.
Some servers that Microsoft successfully restarted became unresponsive again once they began receiving traffic.
This made recovery more difficult. Bringing a server back online did not necessarily mean it could handle normal workloads.
Microsoft also investigated recent network configuration changes and began testing whether reverting them could help restore stability.
By 13 November, the company reported positive results after applying a patch to an authentication and routing configuration component.
However, Microsoft has not yet published a complete root cause analysis.
The available technical updates explain several mechanisms behind the disruption, but they do not establish the final reason the incident began.
How Can a Server Problem Affect Millions of Users?
Microsoft 365 operates across extensive cloud infrastructure distributed through multiple regions.
Under normal conditions, incoming requests are distributed across available systems to keep services responsive.
If some servers stop responding, other servers may need to handle their workload.
Imagine an infrastructure environment with 100 servers handling incoming requests.
If 30 suddenly become unavailable, the remaining 70 must absorb additional traffic.
If those servers are already operating near their intended capacity, response times can increase and connection failures may occur.
This is a simplified example rather than a description of Microsoft’s actual server counts.
During the November outage, Microsoft confirmed that the elevated load was related to servers becoming unavailable, rather than an overall increase in customer traffic.
The company attempted to redistribute connections, restart affected infrastructure, and introduce additional capacity.
These recovery measures needed careful testing because some restarted servers were becoming unresponsive again under load.
This helps explain why restoring a large cloud service can take considerably longer than restarting an individual computer or application.
Why Were Microsoft Teams and Copilot Also Affected?
Many people associate Microsoft Teams with video meetings and Outlook with email.
Although they appear to be separate products, several Microsoft 365 services depend on shared infrastructure and communicate through common systems.
This connection played an important role in the November disruption.
Microsoft Teams
Microsoft reported that most core Teams functionality, including calls, meetings, group chats, and channel messaging, remained operational.
However, features that depend on Exchange Online could fail.
For example, users experienced problems with meeting scheduling, calendar access, invitations, and certain meeting updates.
Teams was therefore not necessarily unavailable in its entirety. The problem affected specific capabilities connected to other Microsoft services.
Microsoft 365 Copilot
Copilot uses information from Microsoft 365 applications to help users work with emails, documents, calendars, and organisational data.
During the outage, some users could not load Copilot Chat or receive responses.
Others experienced problems when Copilot attempted to retrieve information connected to Outlook, calendars, or Microsoft 365 files.
This demonstrated how an issue in an underlying service can affect AI-powered features that depend on it.
SharePoint, Planner and Other Services
Microsoft also identified problems affecting SharePoint-related functions, Planner, To Do, Microsoft Graph, and parts of its security and administration tools.
In SharePoint, for example, access to files stored directly on the platform remained functional, while certain features connected to Exchange Online were affected.
The extent of disruption varied between applications and users.
The important technical point is that software platforms often share dependencies even when their user interfaces and purposes are different.
Was the Microsoft 365 Outage a Cyberattack?
Whenever a major technology company experiences a global service disruption, questions about cybersecurity quickly follow.
The Microsoft outage was no exception.
However, Microsoft has repeatedly stated that it has found no evidence of malicious activity associated with this incident.
Its published investigation has focused on server availability, automated health checks, connection processing, traffic management, and configuration changes.
There has been no confirmed finding that hackers caused the outage.
A software or infrastructure failure can create serious disruption without involving a cyberattack.
Until Microsoft releases its full post-incident report, claims about a definitive cause should be treated cautiously.
What Has Microsoft Done to Restore Its Services?
Microsoft has been working through several technical recovery measures.
One of its first responses was to redistribute traffic across available infrastructure, reducing pressure on affected servers where possible.
Engineers also restarted unresponsive systems and tested alternative ways of checking server health.
When early fixes produced inconsistent results, Microsoft began isolating affected infrastructure and carefully restoring traffic in stages.
The company then tested configuration changes involving secure connections and network routing.
On 13 November, Microsoft reported improving server stability after deploying an authentication and routing configuration patch to portions of its infrastructure.
The patch was being expanded to additional regions after engineers confirmed improvements in the systems where it had already been applied.
Microsoft also increased infrastructure capacity and worked to process delayed email messages.
To help protect messages waiting for delivery, the company extended its email timeout window to 48 hours.
Latest Microsoft 365 Recovery Status
As of approximately 5:30 PM IST on 13 November 2026, Microsoft’s incident updates indicated that recovery was progressing.
The company reported improved mailbox access and email delivery in portions of the Asia-Pacific region. It also observed encouraging progress in Europe and North America, while Japan remained comparatively more stable.
Some users could still experience intermittent problems, and complete service restoration had not been confirmed.
Microsoft has said it will publish a detailed post-incident report covering the root cause and corrective measures after the disruption has been fully resolved.
What Does This Incident Tell Us About Cloud Software?
Most businesses rely on cloud applications because they make communication, collaboration, and data access easier to manage.
However, even a large cloud provider can experience infrastructure failures.
The November Microsoft outage illustrates several important considerations for businesses and software development teams.
System dependencies should be understood.
An application may appear independent while relying on another service for authentication, data access, scheduling, or communication.
When that dependency becomes unavailable, connected functionality may also fail.
Monitoring systems need careful design.
Automated health checks help identify problems, but the systems performing those checks must also function reliably.
Recovery procedures should be tested before an emergency.
Restarting servers is not always sufficient. Applications need controlled recovery processes that verify whether restored infrastructure can safely handle real traffic.
Businesses should prepare alternative communication methods.
If your organisation uses Microsoft 365 for most internal and external communication, employees should know how to contact clients and colleagues when email or scheduling services become unavailable.
Software reliability requires continuous attention.
Testing, monitoring, maintenance, and configuration management all contribute to dependable applications.
These considerations apply to cloud platforms as well as custom ERP systems, CRM applications, e-commerce websites, and other business software.
What Should Businesses Consider When Developing Custom Software?
The incident also raises an important point for organisations planning new software systems.
Businesses often focus on features, design, functionality, and implementation costs during development.
Those are important considerations, but application reliability deserves attention from the beginning.
For example, a manufacturing company developing a custom ERP system should consider what happens if its server becomes unavailable during production or inventory processing.
An e-commerce business should understand how its website handles temporary payment gateway failures.
A company operating a CRM should establish how important customer information is protected and recovered if a connected service becomes inaccessible.
The appropriate solutions depend on the application and its operating requirements.
These may include database backups, application monitoring, controlled deployments, redundant infrastructure, and documented recovery procedures.
At Flutebyte Technologies, we develop custom ERP systems, websites, mobile applications, and business software according to each organisation’s requirements.
We believe that understanding operational dependencies and planning for maintainability and recovery are essential parts of responsible software development.
Final Thoughts
The Microsoft Outlook and Microsoft 365 outage of 12–13 November 2026 has shown how a disruption within cloud infrastructure can affect multiple applications and services.
Microsoft’s investigation identified overloaded connection processes, servers failing automated health checks, and difficulties maintaining stable infrastructure during recovery.
A configuration patch has improved server stability, but the complete root cause remains under investigation.
For businesses, the incident provides a useful reason to review technology dependencies, communication arrangements, and recovery procedures.
Cloud services remain an important part of modern business operations. Understanding their limitations and preparing for possible interruptions can help organisations reduce the disruption caused by unexpected technical problems.
Last updated: 13 November 2026, approximately 5:30 PM IST.
This article is based on Microsoft’s published incident updates and reporting available at the time of writing. Technical findings and service status may change as the investigation continues.
References
- Microsoft Service Health Status
- Microsoft Incident Reports: Exchange Online and Microsoft 365
- Reuters: Microsoft Outage Hits Outlook, Teams and Copilot
- The Guardian: Microsoft Begins Restoring Services
About Flutebyte Technologies
Flutebyte Technologies specialises in custom software development, ERP systems, CRM solutions, web applications, and business technology services.
Learn more at www.flutebyte.com.